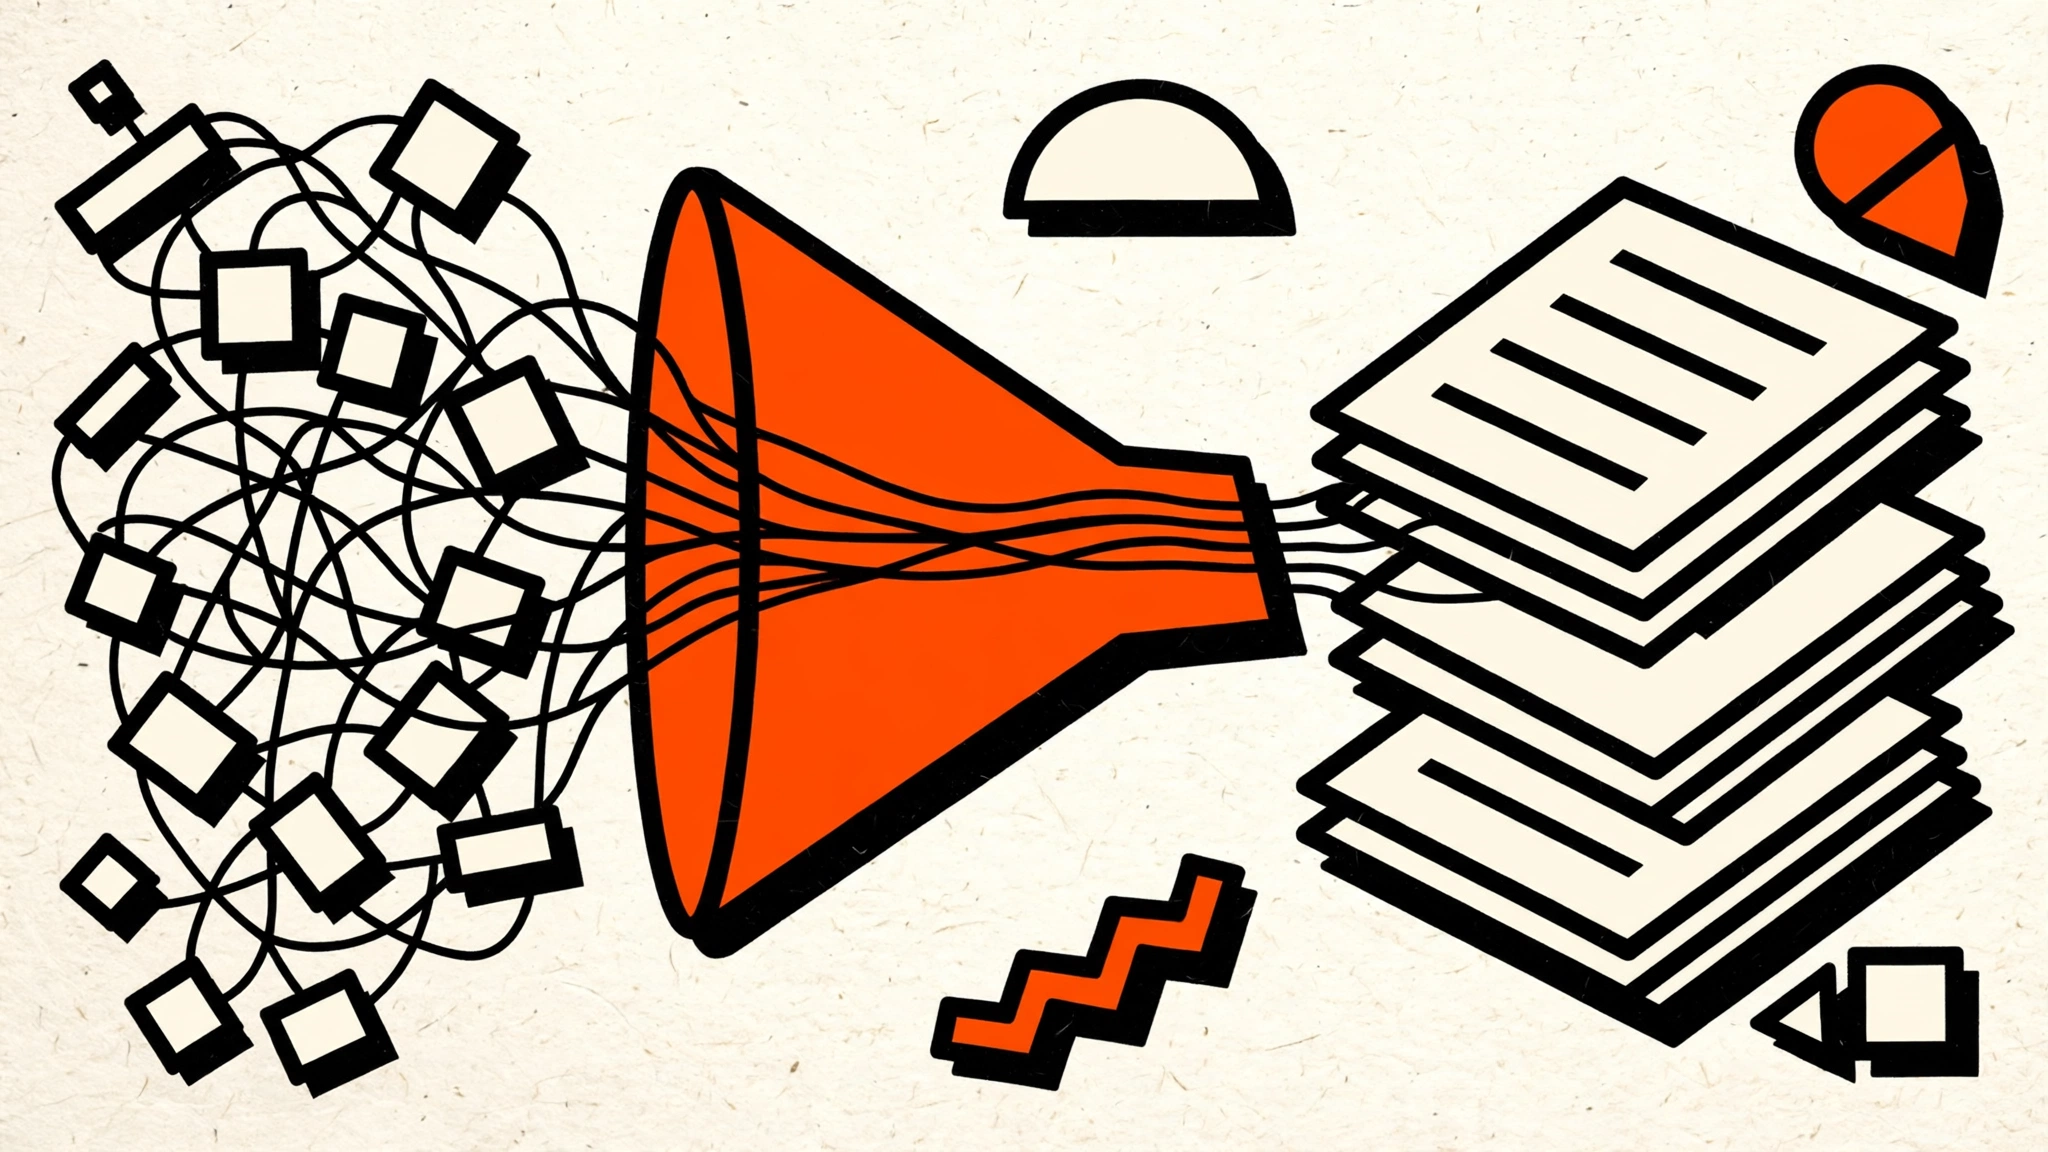
Scraping a bot-protected site is the single most expensive line item in most web-data workflows — proxies, CAPTCHA solvers, browser infrastructure, and the hours you spend babysitting all of it. Apify announced a Web Fetch actor on October 14 that turns the whole problem into a single API call: one URL in, clean Markdown out, even from heavily bot-blocked sites, for $0.0015 per successful fetch. By the end of this article you’ll know the pricing math, the n8n wiring pattern, and the routing-agent idea worth stealing from their new coding-agent plugin.
What Web Fetch actually is
Web Fetch is an Apify Actor (Apify’s word for a cloud program you run on demand) with one job: fetch a URL and return its content as clean Markdown, text, or HTML. It renders JavaScript like a real browser and routes around bot blocking — CAPTCHAs, IP bans, anti-scraping checks — without you managing proxies. You can find it at apify.com/apify/web-fetch, and the Apify MCP server exposes it as the apify--web-fetch tool for AI agents.
Apify says it pulled usable content from 91% of heavily protected URLs in its benchmarks. That number comes from Apify, not an independent test — treat it as the vendor’s best case, not a guarantee. But the actor exists, it’s listed in the Store, and the pricing is public, so the value proposition is checkable: does $0.0015 per successful fetch beat your current stack?
 A developer’s workspace — the code on screen is the cheapest part of most scraping stacks. (Image: Pexels)
The pricing math: $0.0015 vs your self-hosted stack
Let’s be honest about what “scrape it ourselves” costs. A typical DIY setup for protected sites has four line items: residential proxies ($2–$8 per GB of traffic), a CAPTCHA-solving service, headless-browser infrastructure that doesn’t get fingerprinted, and your own maintenance time when sites change their markup next month. Per-page, that usually lands between $0.005 and $0.05 once you account for blocked retries and rebuilds.
Web Fetch charges $0.0015 per successful fetch on the Free and Starter plans, $0.00125 on Scale, and $0.001 on Business (an extra Actor Start event of $0.00005 per GB of memory per run is a rounding error on top). The killer detail: you only pay for successful fetches. Blocked pages — the exact thing that burns money on DIY stacks — don’t bill you. For a pipeline that fetches 10,000 pages a month, that’s $15 on Starter versus the cost of keeping a proxy pool warm.
Note: Pricing numbers above are reported by a third-party pricing comparison published this week, consistent with the actor’s Store listing — check the Store page for the current rate before you commit a budget.
This is not free, and it is not unlimited. The per-fetch model punishes sloppy pipelines that re-fetch pages they already have. Cache aggressively, and only fetch what feeds your agent.
The one-install plugin: what n8n builders should steal
The second half of the announcement is the more interesting one for agent builders. Apify now ships a plugin for coding agents — Claude Code, Cursor, Codex — that installs with one command: the Apify MCP server, ready-to-run skills, and a routing agent that picks the right Actor and fills in its inputs, all through a single sign-in. No API token pasted into a config file.
That routing-agent pattern is the idea worth stealing for n8n. Most n8n scraping setups pick one scraper node and live with it. The Apify approach is a dispatcher: the agent describes what it needs (“search Instagram for bakery leads in Austin”), and the router selects the right Actor from 3,000+ in the Store, reads its input schema, and calls it. You can build the same dispatcher in n8n with an AI Agent node plus a handful of sub-workflows — one sub-workflow per scraper, with the agent choosing between them based on descriptions. The dispatcher’s decision log becomes your audit trail for free.
Apify’s own Hermes agent plugin README shows the shape of this: an actor-routing skill with curated picks for common tasks, loaded before the agent ever searches the Store. Curated defaults beat open-ended search — for your n8n dispatcher too.
Wiring Web Fetch into n8n: the 5-minute version
You don’t need the plugin to use Web Fetch from n8n. The Apify REST API takes a plain POST, so an n8n HTTP Request node is enough. You need an Apify account and an API token (Console → Settings → Integrations).
Step 1 - Start an Actor run. POST to the actor endpoint with the URL you want:
curl -X POST "https://api.apify.com/v2/acts/apify~web-fetch/runs?token=<your-apify-token>" \
  -H "Content-Type: application/json" \
  -d '{"url": "https://example.com/pricing", "outputFormat": "markdown"}'
The response JSON contains a data.id — the run ID you’ll poll for results.
Step 2 - Read the dataset. GET the run’s dataset items (this is the call your n8n HTTP node makes in a Wait/loop or with the Apify “Get dataset items” operation):
curl "https://api.apify.com/v2/acts/apify~web-fetch/runs/<run-id>/dataset/items?token=<your-apify-token>"Step 3 - Verify. The returned JSON should contain your page’s text as Markdown. If status is FAILED, check the run’s log in the Apify Console — the most common cause is a malformed input (wrong actor ID format: note the tilde in apify~web-fetch in REST calls, not the slash).
Warning: Scraping is only half the legal picture. Some sites forbid automated collection in their terms, and personal data you collect falls under GDPR and similar laws. Web Fetch removes the technical block, not the legal one — check the site’s terms for your use case.
 Every scraping pipeline ends with someone reading code. The question is only how much of the plumbing you wrote. (Image: Pexels)
Hard cases and limits — what the announcement doesn’t solve
Honest accounting matters here. First, 91% is Apify’s benchmark, and bot-blocked sites are adversarial: what works today can fail next week when the target changes its defenses. Second, Web Fetch is one page per call — crawling a whole site means orchestrating thousands of runs, and that’s where a dedicated crawler (Apify’s Website Content Crawler, or your own queue-mode n8n setup) still wins. Third, bot-blocking exists for a reason: news sites and social platforms protect their content, and a cheaper way past the block doesn’t make it allowed. Fourth, I haven’t independently tested the actor’s success rate or latency — treat this article’s architecture advice as tested patterns and the vendor claims as vendor claims.
Key Takeaways
- Apify’s Web Fetch actor turns bot-blocked scraping into a $0.0015 API call — one URL in, clean Markdown out, with only successful fetches billed.
- The pricing math beats DIY stacks for most builders: $15 for 10,000 pages/month beats proxies + CAPTCHA solvers + your maintenance time.
- Steal the routing-agent pattern: a dispatcher that picks the right scraper per task (Apify’s one-install plugin does this for coding agents; you can build the same with n8n sub-workflows).
- Vendor benchmarks are starting points, not guarantees — budget for failures and cache aggressively.
Next step: try one URL through the Store page before you wire anything into n8n — if your target site is in the 9%, you want to know that before you’ve rebuilt your pipeline.
Images: Pexels