Your Stripe webhook fired once. The customer got charged twice. The n8n execution log shows two successful runs, one second apart, both with the same event_id.
This is not a bug in your workflow. It is the network being the network: webhook providers resend events when your endpoint answers too slowly, and n8n has no memory of what a previous execution already did. Every redelivery is a brand-new execution that happily charges the customer again.
By the end of this guide you will have an idempotency gate at the front of your webhook workflow — a single Postgres insert with a unique constraint on event_id that atomically rejects duplicates before any side effect runs — plus stable idempotency keys you can pass through to APIs like Stripe that support them.
Prerequisites
- A self-hosted or Cloud n8n instance with the Postgres node available (as of n8n 2.x, Oct 2026).
- A PostgreSQL database your workflow can reach (the same one n8n uses, or a separate one — the pattern works with either).
- A payment/order webhook source that retries deliveries — Stripe, Razorpay, Paddle, or Shopify. Stripe retries failed webhooks for up to 3 days, so duplicates can arrive long after the first delivery.
Why retries create duplicates in the first place
A webhook (an HTTP POST a service sends your n8n workflow when something happens) is delivered with an at-least-once guarantee, not exactly-once. Providers like Stripe treat any non-2xx response — or a response that takes longer than about 30 seconds — as “delivery failed” and resend the same event, same event_id, minutes later.
n8n makes this worse in two ways:
- Every delivery is a new execution. The second delivery of
evt_abc123does not know the first delivery already ran. There is no built-in dedup of webhook events across executions. - Retry On Fail re-runs side effects. If the HTTP Request node that calls your payment API times out after the payment went through, n8n retries the node and charges again — the node reports the timeout as a failure even though the action succeeded.
The community hit this hard: a forum thread on stopping duplicate Stripe charges documents builders solving it with an idempotency-gate pattern — a stable event ID, stored externally, checked before the action runs.
Step 1 - Create the dedup table in Postgres
One table, one column that matters. Run this against your database (psql, pgAdmin, or n8n’s Execute Query node once):
CREATE TABLE webhook_events (
  event_id   TEXT PRIMARY KEY,
  workflow   TEXT NOT NULL,
  received_at TIMESTAMPTZ NOT NULL DEFAULT NOW(),
  status     TEXT NOT NULL DEFAULT 'claimed'
);

CREATE INDEX idx_webhook_events_received
  ON webhook_events (received_at);
What each piece does: event_id is the PRIMARY KEY, which creates a UNIQUE constraint — that constraint is the entire atomicity guarantee. Two concurrent executions can both try to insert the same event_id; Postgres lets exactly one win and rejects the other, with no race condition possible. The received_at index exists only so you can cheaply delete rows older than your provider’s retry window (Stripe: 3 days; most others: 24 hours) — keep event IDs for the full retry/replay window, not an arbitrary few days.
Note: A Google-Sheets-based ledger cannot do this job — a spreadsheet has no unique constraint, so two near-simultaneous deliveries can both read “no row yet” before either writes. Use Postgres (or Redis
SET key value NX).
Step 2 - Put the idempotency gate at the top of your workflow
The gate must be the first node after the Webhook trigger, before anything that touches money, inventory, or customers. Use a Postgres node with an Execute Query operation:
INSERT INTO webhook_events (event_id, workflow)
VALUES ('{{ $json.id }}', 'stripe-payment')
ON CONFLICT (event_id) DO NOTHING
RETURNING event_id;
$json.id is the provider’s event ID (Stripe sends it as id in the webhook body; for other providers use their equivalent field). ON CONFLICT (event_id) DO NOTHING means: if this event was already claimed, insert zero rows instead of erroring. RETURNING event_id returns one item for a new claim and zero items for a duplicate.
Now the gate logic in an IF node right after:
- If the Postgres node returned items → this is a fresh event. Continue to the charge/order nodes.
- If it returned nothing → duplicate. Route to a Respond to Webhook node returning HTTP 200 and end.
A 200 for duplicates is deliberate: the provider retries because it thinks delivery failed, and a fast 200 tells it to stop. Responding 4xx or timing out just manufactures more duplicates.
Warning: When
ON CONFLICT DO NOTHINGhits a duplicate, the Postgres node outputs zero items — and by default n8n does not run anything after a node with no output. If your Respond to Webhook sits on the duplicate branch, it would never execute, and the provider would keep retrying. In the Postgres node’s Settings, turn on “Always Output Data” so the duplicate branch runs and sends its 200. This is the single most common way the pattern silently fails (flagged in the webhook-events forum thread).
Step 3 - Respond fast, process after
The second half of the fix is latency. Slow responses are what trigger most provider retries in the first place, so the webhook should acknowledge immediately and do the work asynchronously.
Set the Webhook node’s Response Mode to “When Received” (respond immediately) and return a small ack like {"received": true}. Then put the Postgres gate and your business logic after it, as the continued execution.
If you have real volume, run queue mode so a slow charge node never blocks the webhook endpoint:
# docker-compose.yml (n8n worker service, n8n 2.x, Oct 2026)
services:
  n8n-worker:
    image: docker.n8n.io/n8nio/n8n:2.39.10  # pin an exact tag in real deployments
    command: worker --concurrency=3
    environment:
      - EXECUTIONS_MODE=queue
      - QUEUE_BULL_REDIS_HOST=redis
      - EXECUTIONS_TIMEOUT=600
What each key does: EXECUTIONS_MODE=queue separates webhook acceptance from execution; command: worker --concurrency=3 lets one worker run three executions in parallel; EXECUTIONS_TIMEOUT=600 kills runaway executions after 10 minutes so a stuck charge doesn’t hold a claim forever.
Step 4 - Give every business action its own idempotency key
The event gate stops the workflow from re-running. But node-level “Retry On Fail” can still re-fire an individual HTTP call that timed out after succeeding. Fix that with a stable idempotency key per real-world action:
- For Stripe, pass the header
Idempotency-Key: stripe-charge-{{ $json.id }}. Stripe’s API deduplicates charges with the same key for 24 hours — a retried request returns the original charge instead of creating a second one. - For APIs without native keys, derive the key from stable data, never from the execution:
{{ $json.id }}-chargeis right;exec-{{ $execution.id }}-chargeis wrong, because a redelivered webhook starts a new execution with a new ID and the check would pass every time.
The rule of thumb: the same real-world action must always compute the same key, on every retry, across executions.
Step 5 - Verify the gate catches a duplicate
You can prove the whole thing works in about two minutes:
- Send the webhook a test payload containing an
event_id(use Stripe CLI’sstripe events triggeror any HTTP client posting to your production webhook URL). - Confirm one
webhook_eventsrow exists and the business action ran once. - Send the identical payload again.
- Check: the second execution should take the duplicate branch, return 200, and the row count in
webhook_eventsshould still be 1.
-- run after the duplicate test; expect count = 1
SELECT event_id, status, received_at
FROM webhook_events
WHERE event_id = 'evt_test_001';
If the count is 2, the PRIMARY KEY isn’t in place — re-check Step 1, because without the constraint this pattern is just a polite suggestion.
What this does not cover
- Uncertain outcomes after a failure. If the charge node fails mid-flight and you don’t know whether the API processed it, don’t just re-run — check the provider’s dashboard or API with your idempotency key first. A retried “maybe” is how double-charges survive even good gates.
- Out-of-order events. A
payment_failedarriving afterpayment_succeededis a sequencing problem, not a duplication problem. Keep astatuscolumn and only transition forward (claimed→charged→fulfilled). - Provider key TTLs. Stripe remembers idempotency keys for 24 hours but retries webhooks for 3 days. Align your own retention to the longer window.
- Cross-region writes. If your workers run in multiple regions, both must hit the same dedup table. A per-region table lets a retried event slip through in the other region.

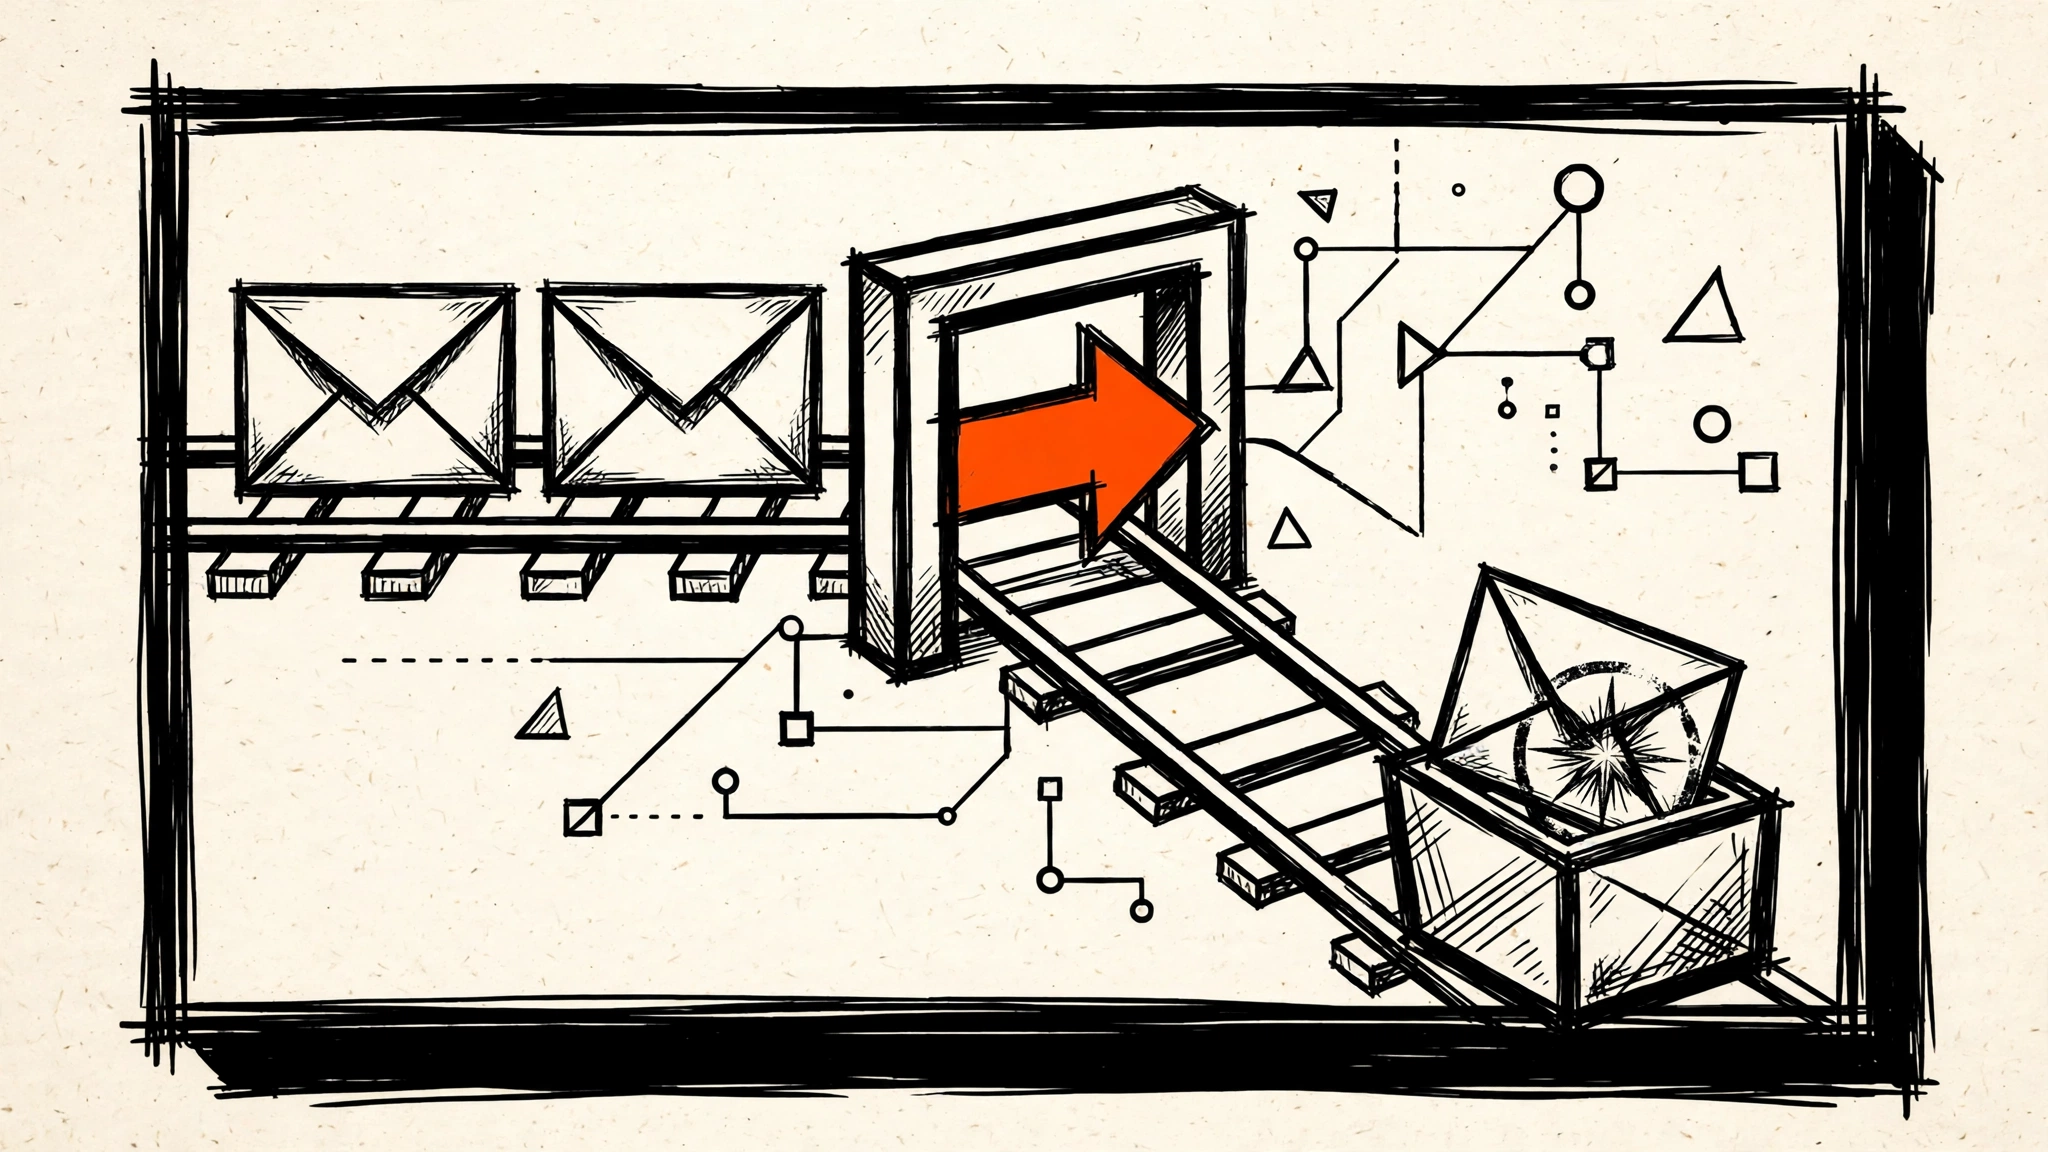
event_id into the ledger drum. Only the first claim opens the orange gate to the output chute — redeliveries of the same event are diverted to the duplicate bin and the provider gets a 200. Watch the ledger drum: that rotating cylinder is the Postgres UNIQUE constraint on webhook_events.event_id, and the single atomic insert is what closes the race-condition hole a lookup-then-write leaves open.When NOT to use this pattern
- Pure read-only or idempotent-by-nature workflows (sync jobs that overwrite the same row) don’t need a gate — adding one just adds a database dependency.
- Events without a stable ID. If the provider doesn’t send a unique event identifier, you must hash the payload into a key (
sha256(canonical_json)) and accept that semantically identical deliveries dedup too. Don’t skip the gate; synthesize the key. - Ultra-high-frequency streams (thousands of events/sec): the insert-per-event overhead is fine for Postgres at this rate, but consider Redis
SET NXwith a TTL instead — one round trip, no table growth, and expiry is built in.
FAQ
Can I use n8n’s own execution list to detect duplicates?
Not reliably. Past executions are queryable via the n8n API, but “check if an execution with this event_id succeeded” is a lookup-then-write — two concurrent deliveries can both read “no execution yet” before either finishes. Only a unique constraint (Postgres) or atomic set-if-absent (Redis SET ... NX) closes that race.
Why not just turn off “Retry On Fail” on the payment node?
That trades one problem for another: without retries, a transient timeout on a payment that never went through becomes a lost order instead of a duplicate. Keep retries on, but make them safe with idempotency keys at the API level and the event gate at the workflow level.
Does this help with queue-mode workers specifically?
Yes — queue mode with multiple workers runs more executions in parallel by design, which makes duplicate deliveries more likely to overlap in time. The atomic claim is exactly what you want when three workers might process the same redelivered event at once.
Should the gate table live in n8n’s own database?
It can, and for small setups that’s simplest — n8n’s Postgres is already backed up. For larger setups, put it in your application’s database alongside the order records so the event claim and the business write can commit in one transaction (a stored procedure called via Execute Query), which is the gold-standard “outbox” version of this pattern.
Key Takeaways
- Webhook retries are at-least-once — providers like Stripe resend on slow or non-2xx responses, and every delivery is a fresh n8n execution with no memory of the last.
- Claim the event atomically before any side effect:
INSERT ... ON CONFLICT (event_id) DO NOTHINGagainst a UNIQUE-constrainedwebhook_eventstable is the gate. Lookup-then-write has a race; unique constraints don’t. - Always Output Data on the Postgres node — otherwise the duplicate branch (and its 200) never runs and retries keep coming.
- Respond to the webhook fast (“When Received”), process after — slow responses are what trigger retries in the first place.
- Keys must be stable across executions: use the provider’s
event_id, never$execution.id, and pass idempotency keys through to APIs that support them.
Next step: add a scheduled cleanup workflow that deletes webhook_events rows older than your provider’s retry window (3 days for Stripe) so the table stays small — and read the webhook-events thread for the outbox variant when your order records share the same database.